Visual Language Models • Neural Voice Synthesis • Subtitle QC & Live Broadcasting
A broadcast-grade, end-to-end media accessibility platform that transforms legacy creative workflows. Built upon over 25 years of global media operations leadership, AT Studio orchestrates local vision-language models (VLMs) and neural speech synthesis to deliver high-margin, studio-compliant Audio Description (AD), live captioning, and automated Quality Control—ensuring unreleased creative IP never leaves sovereign infrastructure.
Legacy media localization and accessibility pipelines are bottlenecked by manual authoring, high freelance overhead, and the existential risk of uploading unreleased video proxies to third-party public AI APIs. AT Studio solves both challenges through air-gapped, on-premise local inference orchestration.
All visual scene understanding (VLMs), speech-to-text models, and text-to-speech neural voice synthesizers run on dedicated local hardware. Unreleased feature films, episodic series, and high-value media assets are processed securely within institutional air-gapped perimeters with zero external telemetry or cloud egress.
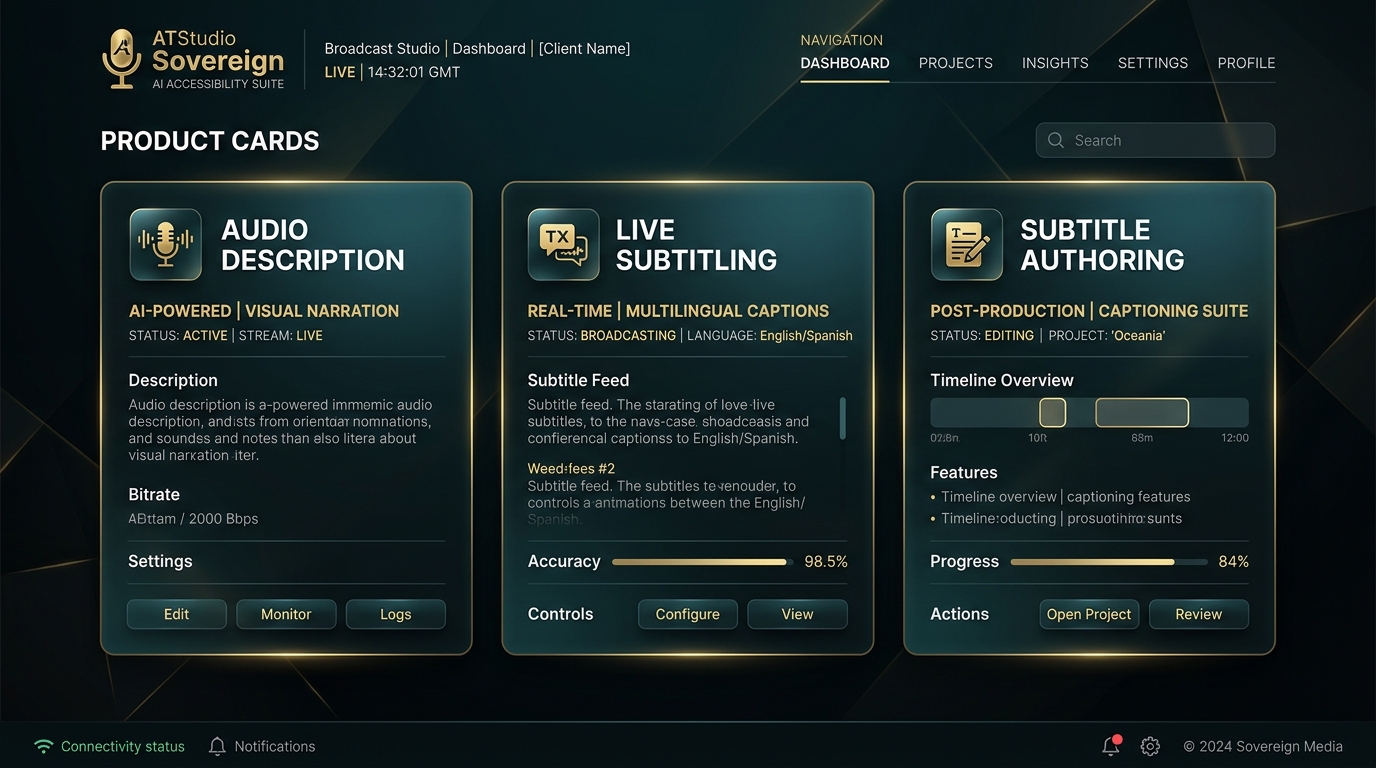
A unified operator interface designed from the ground up for professional audio describers, subtitlers, and broadcast compliance engineers.
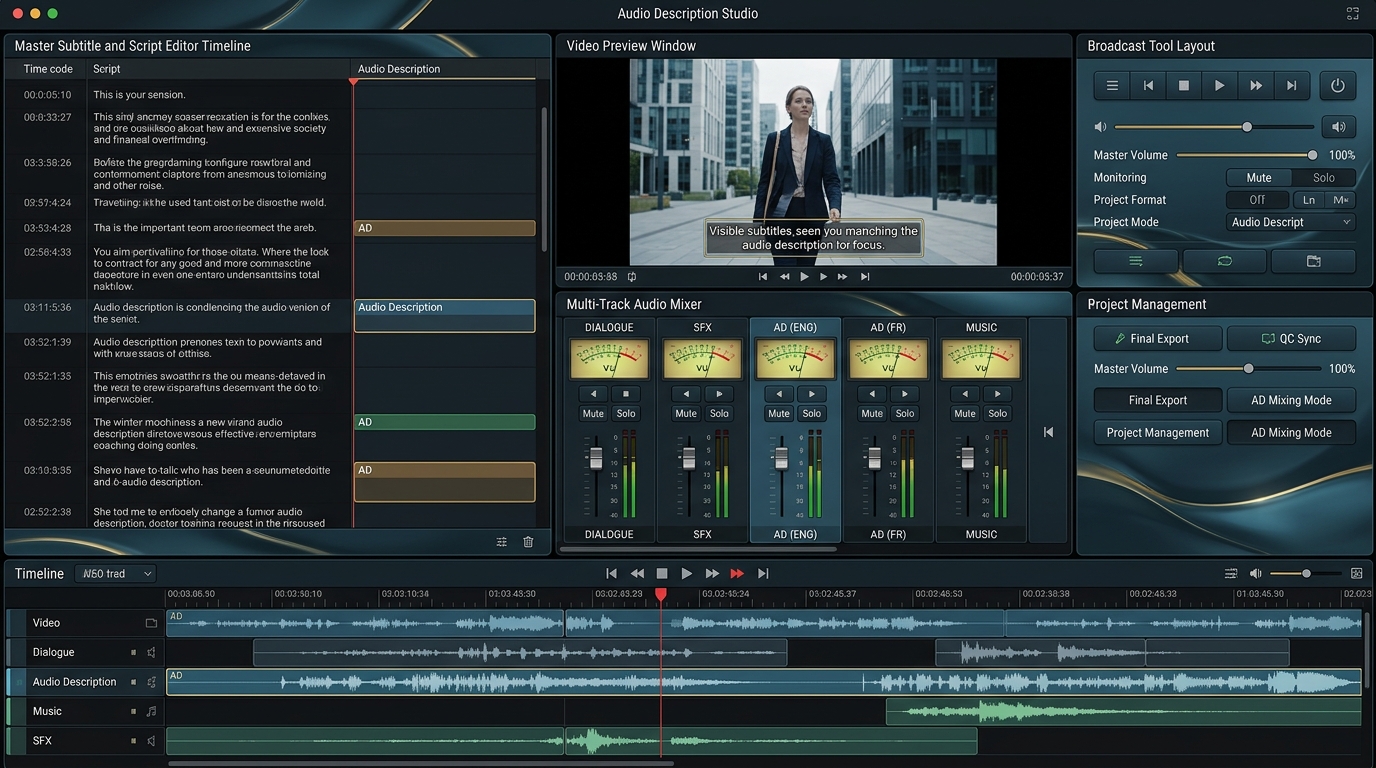
A timeline-synchronized multi-track editor that synchronizes video playback, waveform inspection, dialogue pause detection, and automated VLM-driven visual description proposals.
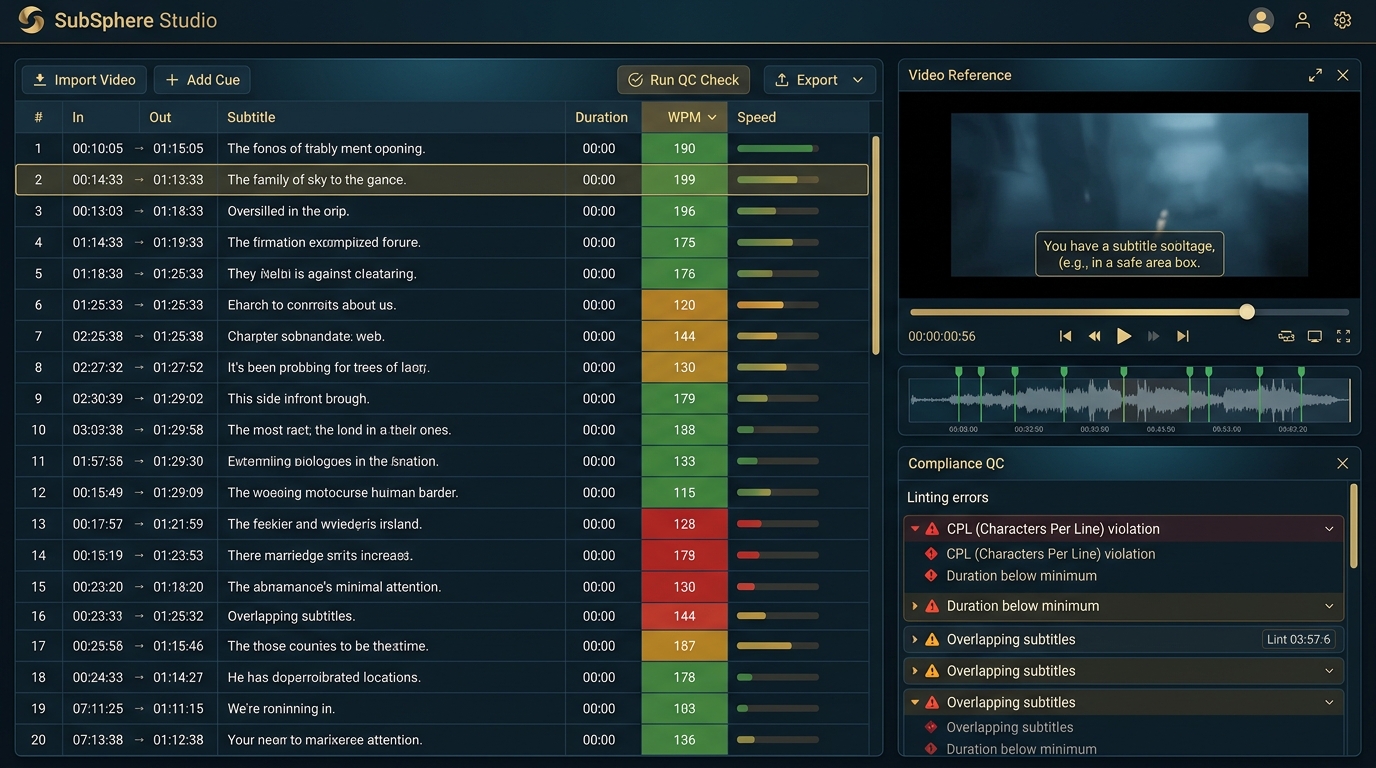
Deterministic automated validation enforcing global broadcast compliance standards (EBU-TT, SMPTE-TT, Netflix Timed Text Specs) in real time before master delivery.
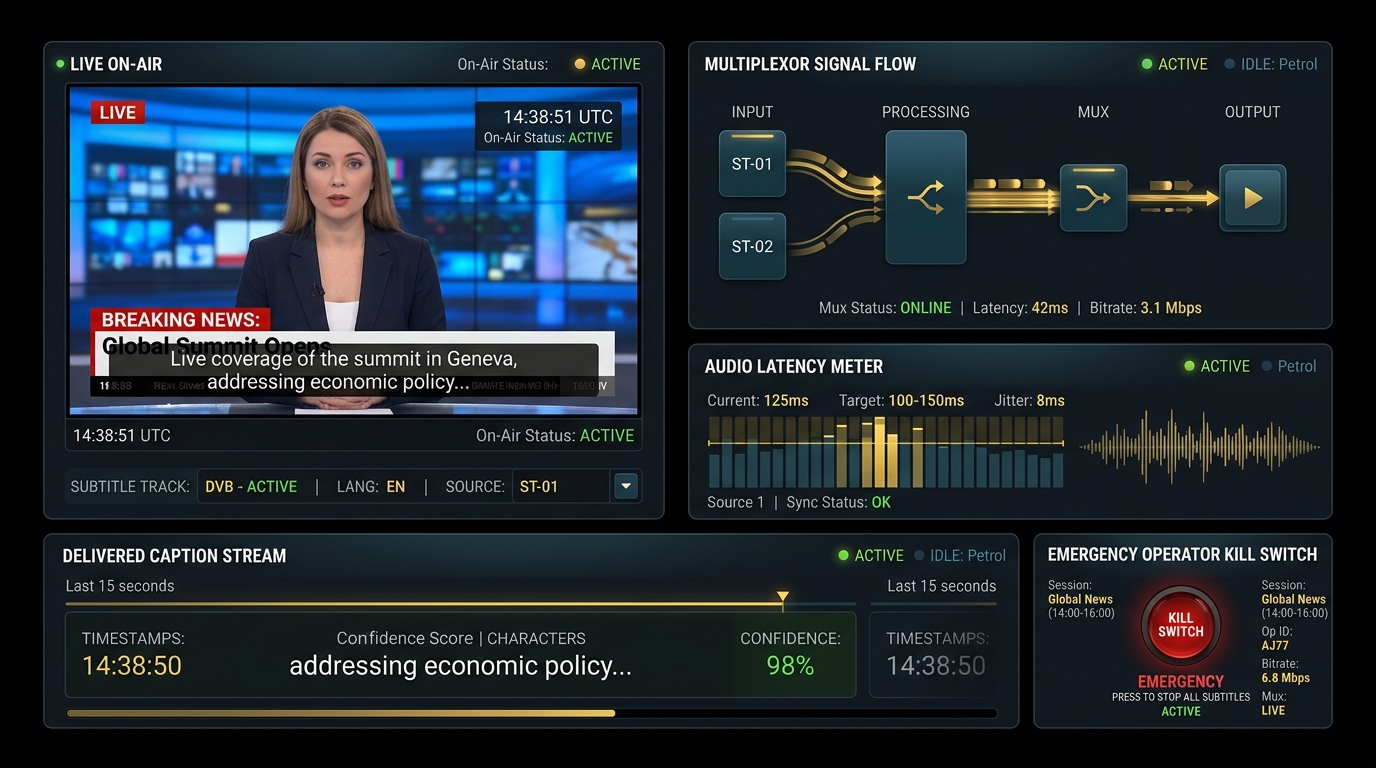
Low-latency streaming captioning engine engineered for live news, sporting events, and real-time broadcast feeds.
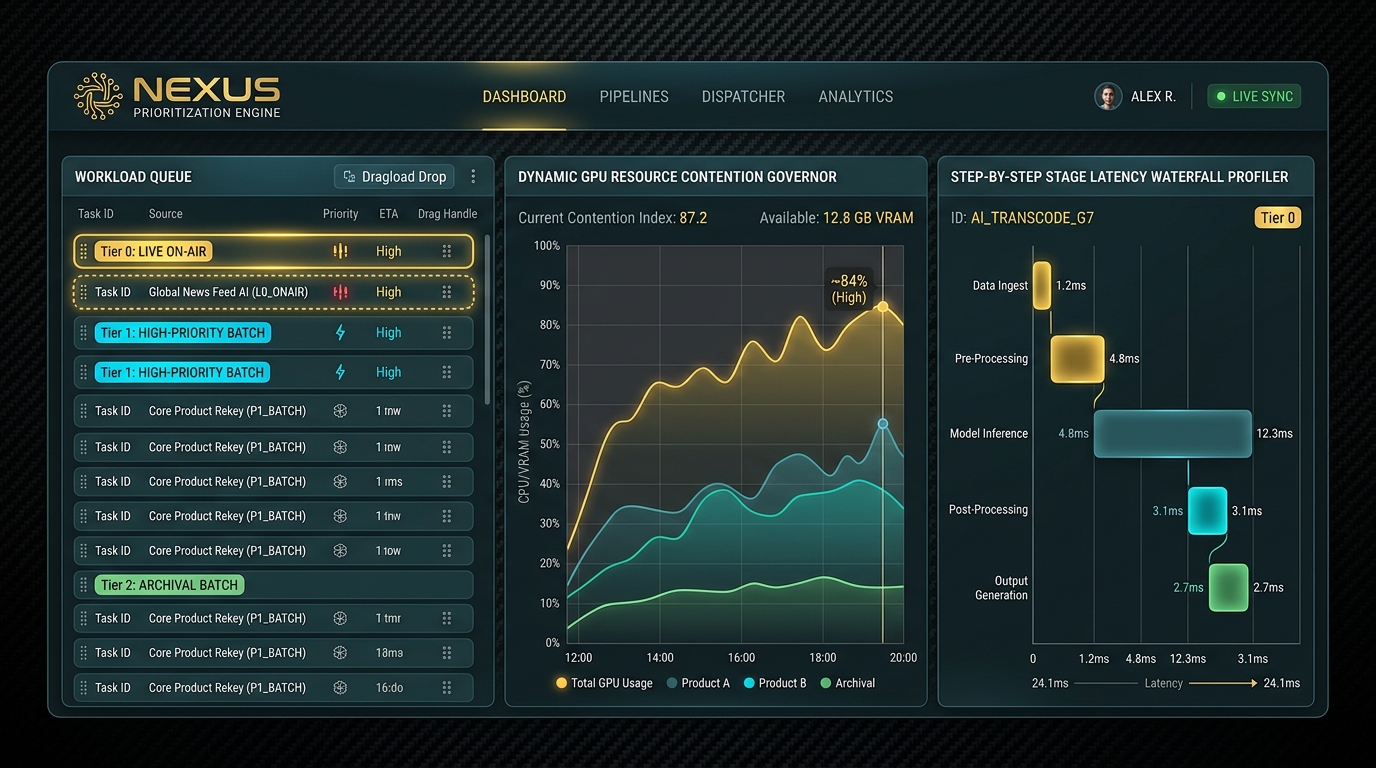
Enterprise job dispatching and asset tracking. Visual Kanban boards manage episodic ingest, batch GPU rendering queues, operator handoffs, and final package exports.
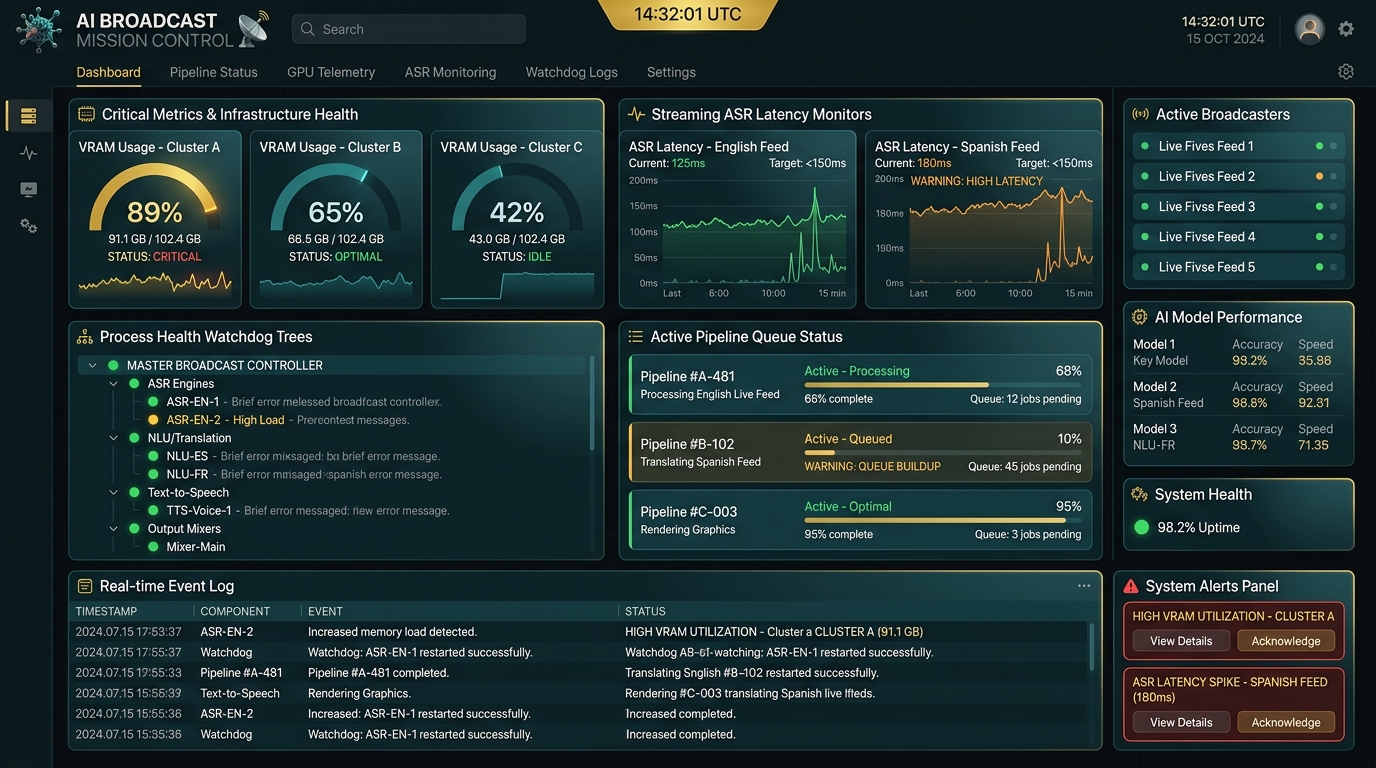
Combining high-throughput GPU inference with intuitive, keyboard-first operator workflows.
Deploying optimized multimodal architectures (Qwen-VL, specialized vision encoders) fine-tuned specifically for cinematic scene comprehension, character identification, and subtle narrative actions.
Broadcast-quality neural speech synthesis with multi-speaker support, expressive prosody controls, and pitch/pacing matching to prevent cognitive clash with master audio mixes.
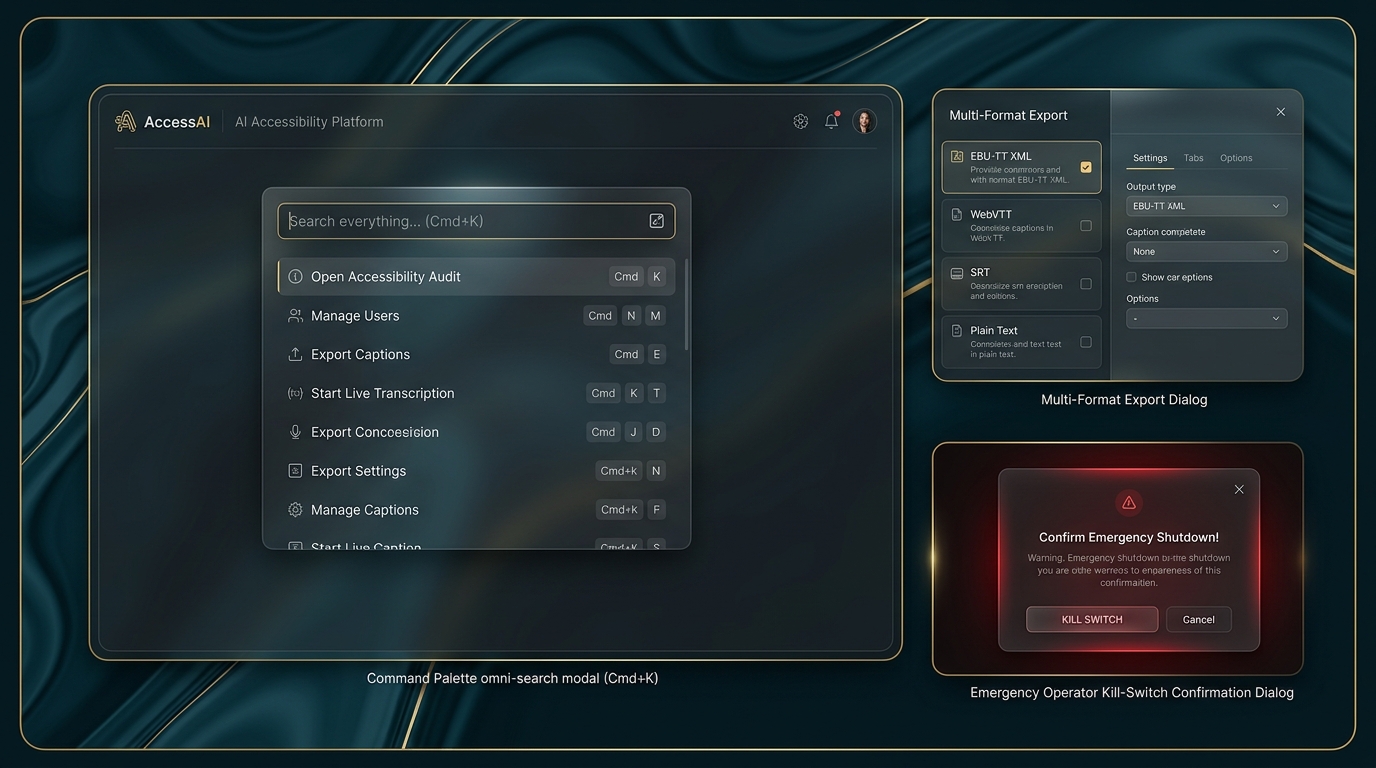
Full keyboard navigation via an integrated command palette and glass modals—enabling professional editors to author, trim, split, and audition cues without touching the mouse.
Real-time monitoring of GPU VRAM allocation, VLM token throughput, audio render latencies, and batch queue health.
High-efficiency modal overlays for rapid cue configuration, voice profiling, and broadcast compliance presets.
Built to satisfy the stringent accessibility regulations and technical requirements of European, North American, and global streaming platforms.
Full support for timed-text interchange standards, styling profiles, regional positioning, and broadcast distribution manifests.
Broadcast-standard multi-channel audio delivery with automated ducking control signals and separate descriptive audio stems.
Direct compliance support for EAA mandates requiring universal accessibility across audiovisual media services and digital platforms.
Interested in learning more about sovereign media accessibility pipelines and air-gapped GenAI architectures?
Contact for Consultation