Decoupled Acoustic Articulation • Emotional Prosody • Co-Speech Body Kinematics
A state-of-the-art conversational digital human framework engineered to transcend the limitations of conventional phonetic lip flapping. Featuring a decoupled two-tier neural architecture, the system combines high-fidelity facial articulation driven by emotional voice inflection with a secondary kinematic model generating natural upper-body and hand co-speech gestures. Supported by an automated parallel training harness engineered specifically for high-accuracy Spanish visual lip-sync and objective SyncNet validation.
Legacy generative lip-sync systems (such as vanilla Wav2Lip) are inherently constrained by design: they learn purely mechanical phonetic mappings without emotional affect, render low-resolution mouth crops that blur when composited into 1080p, and leave the body frozen—resulting in the classic "uncanny valley."
To achieve true photorealism, the system separates facial speech synthesis from body presence into two specialized, acoustically coordinated neural models:
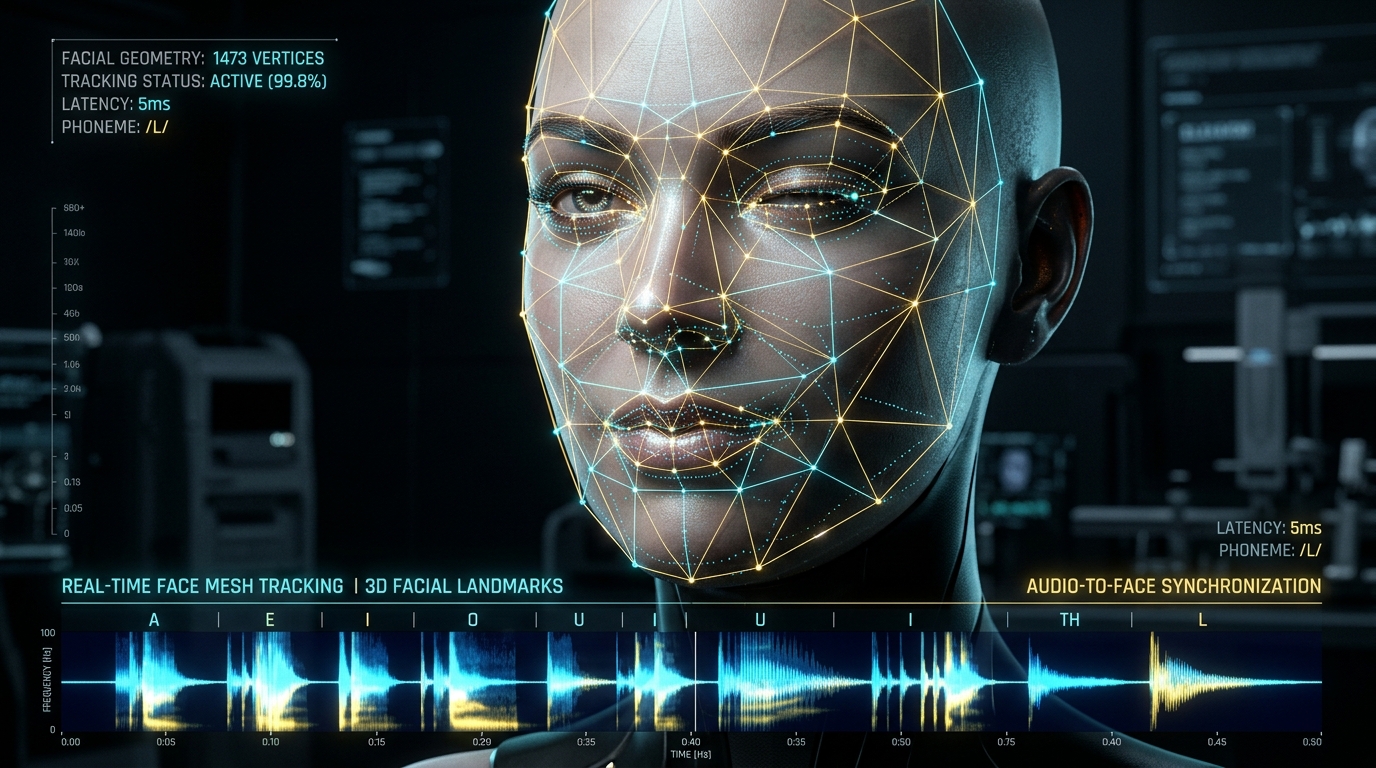
Synthesizes sub-pixel mouth visemes, micro-expressions, and eye-gaze dynamics conditioned on speech prosody, vocal pitch contour, and emotional inflection.
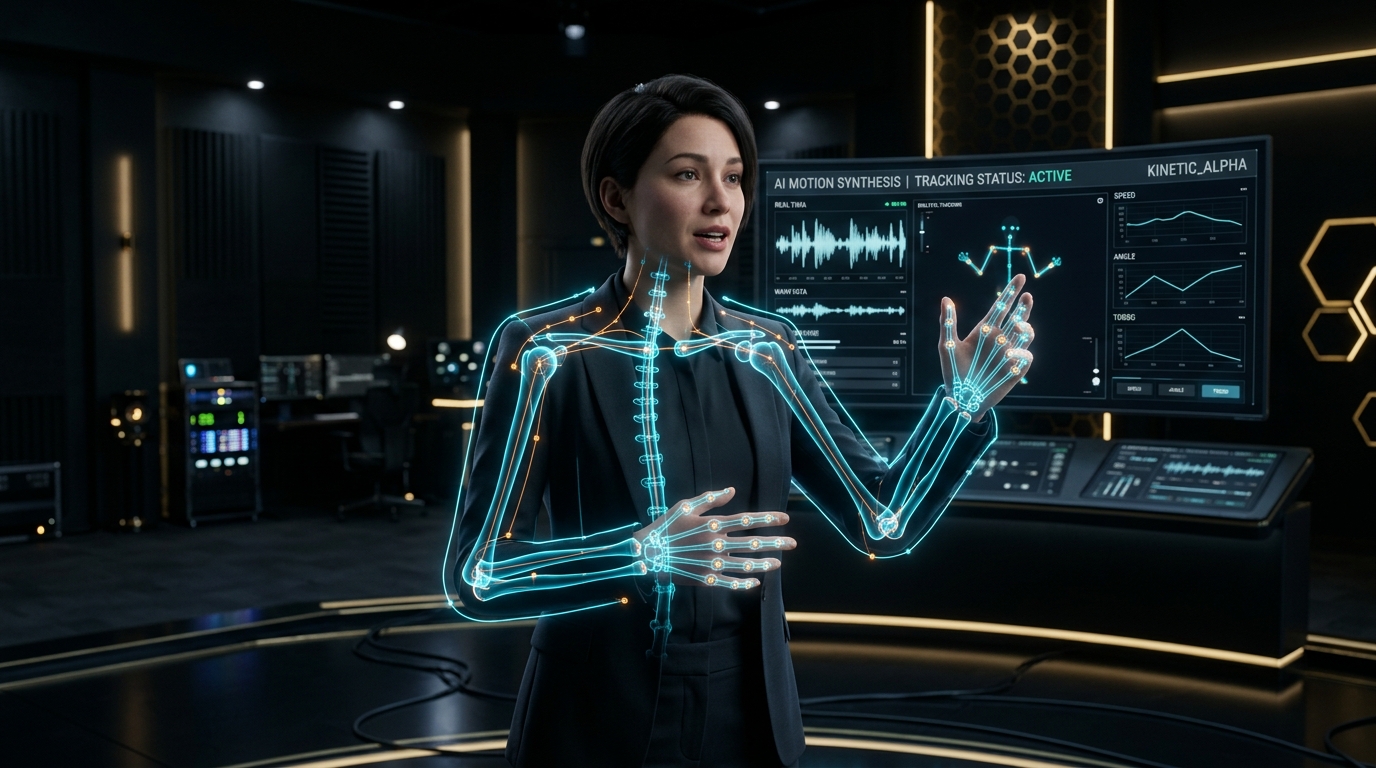
Extracts and synthesizes synchronized shoulder shifts, neck posture, and natural conversational hand gestures derived directly from the rhythm and cadence of speech.
Human communication is multimodal: we speak with our hands, shift our weight, and emphasize points with head tilts. The kinematics engine extracts skeletal keypoints across wide-angle reference footage to train an upper-body motion model that animates the avatar organically without manual keyframing.
The foundation of high-precision lip-sync is specialized training data and an uncompromised preprocessing harness. This parallel project established an automated ingestion, curation, and validation pipeline tailored specifically for Spanish acoustic phonetics.
Fixed-box crops degrade lip-sync models: natural head movements drift off-center, causing models to learn blurred approximations. The pipeline incorporates per-frame landmark tracking with dual-window temporal smoothing:
Moving beyond subjective visual inspection, the pipeline employs mathematical verification and high-resolution composite rendering.
Mathematical cross-modal evaluation calculating Audio-Visual (AV) synchronization offsets and confidence scores, ensuring models meet broadcast synchronization standards before deployment.
Advanced Poisson blending and color-matched edge transitions prevent the visible seams, color disparity, and boundary blur common when inserting generated crops back into 1080p master scenes.
Designed to execute entirely on sovereign GPU clusters without relying on third-party cloud avatar APIs, ensuring enterprise conversational interactions remain completely confidential.
Interested in deploying custom digital human pipelines, speech-driven facial animation, or sovereign vision architectures?
Contact for Consultation